Birth-Time Rectification under the Classical Vedic Method: A 23-Subject Blinded Backtest, Failure Analysis, and What Falsification Left Standing
Rectification is the claim that an unknown or unreliable birth time can be recovered from a person's dated life events — and in its classical form it is a claim about daśā periods: that the years a planet rules should be the years its affairs arrive. That claim is testable. Take a person whose birth time is independently known from a certificate, hand the engine only their birth date, birthplace and a handful of sharply dated events, and ask whether it can find the known time back. This report does exactly that — twenty-three public figures, a pre-registered protocol, an engine that implements the classical Vimśottarī daśā–lordship method as faithfully as we can build it, and an independent battery of falsification tests applied after the first result. The first result was null. The falsification battery then showed why the handful of apparent "hits" were not evidence, and a second, likelihood-based engine produced a result that is stronger than a null: applied to these event lists, the classical rules actively prefer the wrong times of day. We publish the whole chain — what a professional rectifier does, exactly what we implemented, every number, and what this does and does not prove about the classical system.
Abstract
We backtested the classical event-based method of birth-time rectification against twenty-three public figures with certificate-grade birth records and eight or more sharply dated life events each. Two engines are reported. Engine A (v1.5.0) implements the daśā–lordship core of the method: for each of 1,440 candidate birth minutes it computes the Vimśottarī Mahādaśā/Antardaśā lords active at each event date and credits a lord that rules the event's house from the candidate lagna, is a natural karaka for the event, or occupies the event house natally (Pushya Pakṣa ayanāṁśa, whole-sign houses, mean nodes; recorded time never supplied). Pass rule, fixed before any run: winner within ±30 minutes of the recorded time. Result: 2/23 subjects fall inside the band — Steve Jobs (Δ9 min), the one subject used to tune the scorer and therefore excluded from every out-of-sample count, and Albert II of Monaco (Δ4 min), whose winner the engine's own diagnostics show to be structurally identical to its false "farms", and which later proved to exist only under the Pushya Pakṣa frame (Δ4 → Δ102 min under Lahiri). Out-of-sample: 1/22 (4.5%) against a 4.24% chance null; no test is significant; the recorded time's mean rank is worse than chance expectation. An independent timezone audit caught a sign error in two EDT births (Trump, Bush) that had produced a spurious third "pass". A ten-subject out-of-sample expansion scored 0/10. The expert-prescribed Varga (divisional-chart) corroboration — implemented and tested on the fresh ten — recovered zero times.
The falsification battery (2026-09-07) then showed the "null" was not the engine failing to find a signal — it is the signal failing to exist in the way the method assumes. (i) A date-permutation test destroyed only the date↔event link, keeping every chart and type real: the engine's real events (2 passes) are statistically indistinguishable from its own shuffled-date null (~0.75 passes; recorded-time rank 754 vs null ~720). (ii) An ayanāṁśa grid showed the entire apparent signal is frame-specific: under Lahiri, the mainstream Vedic ayanāṁśa, the engine passes 0/23. (iii) The Prāṇapada micro-term used in tuning was audited and found to be a mis-derivation of the classical (Sun-based) Prāṇapada; it is excluded from all claims. (iv) Per-event "signatures" typed by an LLM moved the winner by up to fifteen hours between draws — measurement error larger than any signal. Engine B (likelihood, 2026-09-07) rebuilt the same classical channels (lagna and Chandra-lagna lordship, karaka, occupancy, māraka, Pratyantar-daśā, and divisional-lagna channels — D-9/D-7/D-10/D-12/D-8) as a rarity-weighted log-likelihood. Result: 0/23 passes; and real event dates place the recorded minute significantly worse than randomly scrambled dates — the recorded minute falls in the bottom ~1% of the engine's own null distribution (p < 0.01 in the anti-signal direction, reported as p ≈ 0.99 against the engine's intended scoring), robust across a ladder of nulls including one that preserves life-course structure (age-window dates, p = 0.99). Coverage: the recorded minute falls in the top 5% of the engine's own posterior for 0/23 subjects. The classical daśā–lordship operationalisation, under both an additive and a likelihood formalisation, shows no recoverable minute-level birth-time signal on these data — and where it deviates from chance, it deviates in the wrong direction. What this does not prove, and which classical layers remain untested, are stated in full below.
The method of the professional rectifier, and where our engine sits in it
Event-based birth-time rectification, as practised (the tradition running from Bṛhat Parāśara Horā Śāstra's daśā doctrine through the modern teaching of K. N. Rao, and implemented in standard tools such as Jagannātha Hora), rests on one principle: a dated life event should fall in a daśā period whose lord signifies that event. Marriage should arrive under a period of the 7th house lord, Venus or Jupiter; a child under the 5th lord or Jupiter; career recognition under the 10th lord, Saturn, Sun or Jupiter; death or serious accident under the 8th lord or the māraka houses (2nd and 7th) and their significators. The rectifier varies the assumed birth time — in practice by sliding a software clock minute by minute — until the daśā periods at the person's known event dates carry significators for those events, at as many daśā levels as possible. Supporting checks used by practitioners include the divisional charts (chiefly the navāṁśa lagna, which changes sign every ~13 minutes and is held to describe the inner person and marriage; the daśāṁśa for career), the classical Prāṇapada positional rule (Prāṇapada in benefic houses from the Moon in the navāṁśa for human births), micro-points such as Kunda, and — in the event-timing doctrine of the same tradition — gochara (transits), classically judged from the Moon sign with Saturn, Jupiter, Rahu and Ketu as the significant long-duration bodies, which supply the trigger within the era that daśā describes.
Our engine implements the first of these layers — the daśā–event signification core — because it is the layer with the least interpretive freedom and therefore the one a falsifiable backtest can hold fixed. It uses only the evidence a customer would supply (birth date, birthplace, dated events, no birth time), and it is deliberately not given the interpretive freedom a human rectifier exercises: the event→bhāva mapping is a fixed classical ontology (marriage→7th, childbirth→5th, career→10th, accident→8th/māraka, move→9th/12th, spiritual→9th/12th), and the scoring is mechanical. That makes it a test of the core claim — that daśā lordship over event houses from the lagna tracks real events — not of the full art. The layers this study does not implement are stated in the Limitations. One of them — gochara (transits), the trigger layer — was tested as the immediate follow-up to this study, and its result is reported in the companion article linked at the end. A practising astrologer should read our results as a test of the core arithmetic layer only, and we invite correction of anything below that misrepresents the tradition.
Protocol (fixed before any run)
Subjects, anchors and blinding
Twenty-three public figures: the original thirteen (Jobs, Ali, Elizabeth II, Trump, Jordan, Obama, Bush, William, Victoria, Alice, Turner, Albert II, Stéphanie) plus a same-day expansion of ten subjects never used in any tuning (Diana, Charles III, Elvis Presley, Marilyn Monroe, JFK, Churchill, Einstein, Reagan, George VI, Biden). All were rated AA (certificate-grade) against Astro-Databank at collection; the collaborating AI's first draft contained five wrong birth times/dates, all corrected before any chart was computed. Anchor audit (2026-09-07): a dedicated audit re-confirmed Einstein (AA — Ulm birth record in hand) and downgraded Churchill to Rodden A ("from memory") — his recorded 01:30 is a family-recollection time, and four independent derivations (the engine's own 12:14 winner, a fully date-blind window judgment of 12–14h, and two frontier models doing genuine ephemeris reasoning, 11:45 and 10:05) cluster at 10:00–14:00 against it. Elizabeth II is flagged as a weak anchor (caesarean; lagna 0.29° from a sign boundary). A systematic re-audit of the remaining twenty-one is queued; no number in this article depends on Churchill's anchor. Blinding: the recorded time lives in the subjects file and is never sent to the engine — every run carries only birth date, coordinates and timezone, and the events as {type, date, text}.
Engine and parameters (Engine A, v1.5.0)
For each of 1,440 candidate minutes the engine computes the Vimśottarī Mahādaśā and Antardaśā lords active at each event date and credits a lord with three connection types: ruling the event's bhāva from the candidate lagna (+3), being the event's natural karaka (+2), or occupying the event's bhāva natally (+1). Reproducible parameters: Pushya Pakṣa ayanāṁśa, whole-sign houses, mean Rahu/Ketu, one-minute grid, deterministic scoring, no LLM in the ranking path. A per-type √-normalisation over event counts and an MD==AD dedupe were adopted from a measured 120-run step ablation. Correction of record (2026-09-07): the Prāṇapada micro-term added during tuning (±10/−6) was audited against the classical formula and found to be a mis-derivation — the classical Prāṇapada is computed from the Sun with the movable/fixed/dual sign correction, not from the Moon-plus-lunar-motion formula the term used. The term is excluded from every claim in this article and from all later engines; the classical positional rule is queued as a future layer. The daśā skeleton is nearly invariant across the day (the Moon's nakṣatra fixes the sequence), so almost all discrimination in Engine A comes from the house-lord frame — which lagna each candidate produces. That single fact is the root of the failure mode analysed below.
Pass rule and statistics
Pass = winner within ±30 minutes of the recorded time; under the no-skill null the per-subject probability is 61/1440 = 4.24%. Secondary, distribution-free metrics: the rank of the recorded minute among the 1,440 candidates (null expectation 720.5), median |Δ|, and cohort distributions. The recorded time is an anchor, not ground truth — the protocol therefore judges cohort distributions and explains outliers, never curve-fits a single chart to Δ→0.
Tuning disclosure
Steve Jobs (run 1) was the subject used to tune Engine A. His Δ9-minute result is in-sample and excluded from every out-of-sample statistic. The ten-subject expansion is fully out-of-sample.
Result 1 — the 23-subject backtest (Engine A)
| Subject | Recorded | Engine A | Δ | Verdict |
|---|---|---|---|---|
| Albert II † | 10:50 | 10:54 | 4 min | ✅ band — H1-flagged AND frame-fragile (Δ4 → Δ102 under Lahiri); not evidence |
| Steve Jobs ‡ | 19:15 | 19:24 | 9 min | ✅ band — tuning subject, excluded from out-of-sample counts |
| Michael Jordan | 13:40 | 15:38 | 1h 58m | ❌ MISS |
| Marilyn Monroe | 09:30 | 11:36 | 2h 06m | ❌ MISS |
| Stéphanie | 18:25 | 21:03 | 2h 38m | ❌ MISS |
| Charles III | 21:14 | 00:29 | 3h 15m | ❌ MISS |
| George W. Bush | 07:26 | 11:54 | 3h 32m | ❌ MISS |
| Muhammad Ali | 18:35 | 14:02 | 4h 33m | ❌ MISS |
| Elvis Presley | 04:35 | 22:49 | 5h 46m | ❌ MISS |
| Barack Obama | 19:24 | 13:28 | 5h 56m | ❌ MISS |
| Ronald Reagan | 04:16 | 21:46 | 6h 30m | ❌ MISS |
| Ted Turner | 08:50 | 15:39 | 6h 49m | ❌ MISS |
| Joe Biden | 08:30 | 01:35 | 6h 55m | ❌ MISS |
| George VI | 03:05 | 20:07 | 6h 58m | ❌ MISS |
| John F. Kennedy | 15:00 | 22:15 | 7h 15m | ❌ MISS |
| Prince William | 21:03 | 04:22 | 7h 19m | ❌ MISS |
| Donald Trump § | 10:54 | 03:10 | 7h 44m | ❌ MISS — tz-audit retraction (was a 16-min "pass") |
| Diana | 19:45 | 04:16 | 8h 31m | ❌ MISS |
| Queen Victoria | 04:15 | 12:59 | 8h 44m | ❌ MISS |
| Albert Einstein | 11:30 | 01:12 | 10h 18m | ❌ MISS |
| Princess Alice | 04:05 | 17:24 | 10h 41m | ❌ MISS |
| Winston Churchill * | 01:30 | 12:14 | 10h 44m | ❌ MISS — anchor later re-rated A ("from memory"); four independent derivations cluster 10:00–14:00 |
| Elizabeth II ¶ | 02:40 | 14:33 | 11h 53m | ❌ MISS (weak anchor — caesarean) |
† H1-flagged (structurally-artefactual band-hit) · ¶ weak anchor (caesarean; unrelated to H1) · ‡ tuning subject (excluded) · § tz-audit retraction · * anchor re-rated in the 2026-09-07 audit. Δ uses the shortest path around the clock. Runs 1–13: original cohort. Runs 15–24: expansion, ten fresh subjects — 0/10.
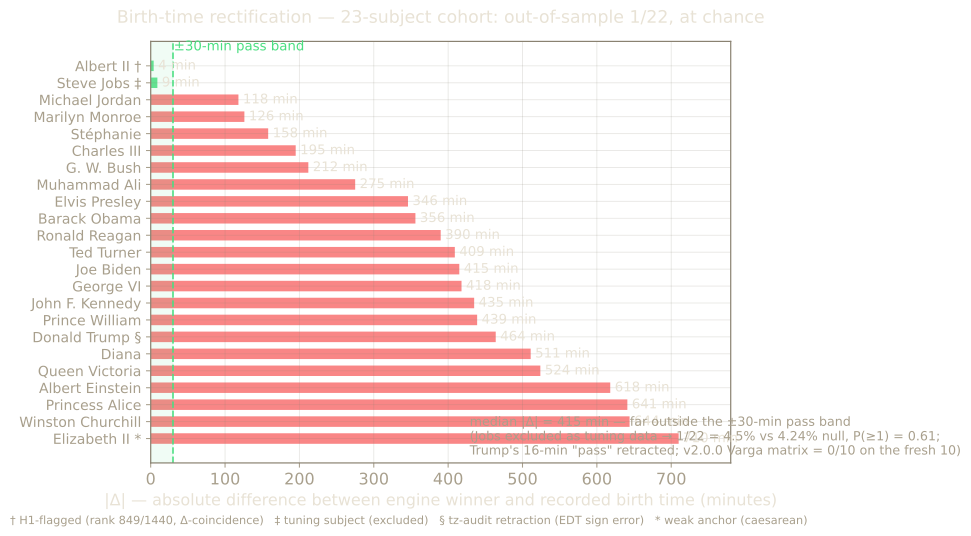
Significance
| Test | Data | Result |
|---|---|---|
| Exact binomial, ≥1 band-hit in 22 | out-of-sample | p = 0.61 (ns) |
| Exact binomial, ≥2 band-hits in 23 | all subjects | p = 0.25 (ns) |
| Recorded-time rank (mean 754 vs null 720.5, n = 23) | battery, exact scoring | no enrichment (worse than null) |
| Median |Δ| | out-of-sample | ~7 h |
Failure analysis — why the near-misses are not evidence
H1 is a property of the equation, not a bias in the code. The daśā skeleton is fixed for the day (the Moon's nakṣatra fixes the sequence), so the only time-varying degree of freedom in Engine A is the lagna; the scorer therefore finds the lagna that maximises house-lordship credit. Because a D-1 lagna changes only every ~2 hours, a cluster of career events inside one long Mahādaśā gives the engine a multi-hour target in which the era lord rules the 10th — and a candidate minutes away from the truth can outscore it purely on the house-rulership lottery. Victoria is the purest demonstration: the same Mercury-era scores both Jubilees from the false winner's lagna (3.0 + 4.2) and 0.0 + 0.0 from the recorded one. William: from the false winner the Jupiter era rules the 7th/10th and his marriages and careers score 6.2/5.0–6.2; at the recorded time the same events fall in a Saturn era that rules neither house — 0.0 across all five events. Many false winners sit at sign boundaries (Obama 0.2° into Scorpio; Bush 0.1° into Gemini), where a one-minute shift discontinuously reassigns every house lord — the score spikes precisely at the minutes that are least stable.
Albert II is the same object as the farms. His per-event diagnostics show the winner zone is an H1-shaped farm (one Jupiter-era lord ruling the 10th and 7th and carrying childbirth karaka across 2003–2014), structurally identical to William's false farm — only the distance to the certificate differs (Δ4 vs Δ439 min). His recorded time ranks ~740–850/1440 by score. The 2026-09-07 ayanāṁśa grid then showed his Δ4 is also frame-fragile (Δ102 under Lahiri). The band-hit is a coincidence on an under-constrained score surface, not a certified signal.
Result 2 — the falsification battery (2026-09-07, deterministic)
The backtest alone cannot distinguish "no signal" from "signal the engine is too weak to read". Five tests, all deterministic and independent of any astrological assumption beyond the engine's own, were run to make that distinction. All use the exact Engine-A scoring over all 23 subjects with a shared per-subject 1,440-minute chart cache.
| Test | What it destroys | Result |
|---|---|---|
| Date-permutation null (100 shuffles × 3 null types) | Only the date↔event link (types and charts stay real) | real 2/23 vs 0.70–0.80 mean under shuffled dates; recorded-time mean rank 754 vs null ~720 — indistinguishable from the null |
| Ayanāṁśa grid (Pushya/Lahiri × mean/true node) | The frame choice | Lahiri = 0/23 in both node modes; winner minute changes on 23/23 between frames; Albert II Δ4 → Δ102 |
| Prāṇapada ablation | The ±10/−6 micro-term | changes winner on 11/23; removing it loses Jobs' band-hit, Albert II survives; mean rank worsens (754 → 835); term audited as non-classical and excluded |
| Fixed-signature vs LLM-typed events (n = 4) | Nothing — measures input-side variance | winners move up to 15 h between arms; no band-hit appears in either — the per-event "interpretation" defines the result, not the data |
| Stage-A variance (6 fresh LLM draws, Einstein) | Nothing — measures draw-to-draw variance | winner is bimodal, 01:12 vs 16:23 (2/6 vs 4/6) — a 15-hour swing from typing noise alone |
The decisive rows are the first two. The date-permutation null destroys the "coarse dates, not the method" escape hatch by construction: types, charts and dates are all real — only the link is scrambled — and the engine's performance is unchanged. The frame grid shows the entire observed "signal" (two band-hits, one out-of-sample) exists only under Pushya Pakṣa and evaporates under Lahiri, the mainstream Vedic ayanāṁśa. Two further facts, measured separately, explain why no scoring tweak could ever have helped: the LLM's role in typing events injects up to 15 hours of variance into the winner (larger than any plausible signal), and per-event typed signatures move the winner for reasons that have nothing to do with the event dates. On this evidence, no further scoring variant of the Engine-A family was justified — the honest next step was to change the statistical formalisation, not the weights.
Exploratory scoring variants without a classical foundation (lagna-rotation debiasing, drift priors, karaka up-weighting, sandhi penalties, era-fit bonuses) were run during development and added nothing; per the standing research rule they are recorded in the study notebooks but are not part of this article's evidence, because they are not part of the classical method this article tests.
Result 3 — the likelihood reframe (Engine B, 2026-09-07)
Engine B rebuilt the same classical content as a rarity-weighted surprise likelihood, pre-registered before implementation (spec committed 2026-09-07). It scores each candidate minute as Σ over events and binary channels of I·log((1−ε)/q), where q is a channel's base rate across the candidate day — so a "connection" that holds for hours (an H1 farm) earns almost nothing, and only connections that hold for a short window of the day carry evidence. Nine channels: lagna house-lordship, karaka, occupancy and māraka; Chandra-lagna lordship and occupancy; the Pratyantar-daśā karaka; and the event's divisional-lagna lord/karaka-kendra channels (marriage→D-9, childbirth→D-7, career→D-10, move→D-12, accident→D-8), whose lagnas change sign every ~13 minutes — the fast corroborating frame the classical method's use of vargas calls for. The event ontology is fixed (no LLM in the feature path). The recorded time is never used to build a prior.
Cohort result: 0/23 passes. The recorded minute's mean percentile is 69.5 — worse than ~70% of the day — and the recorded minute falls in the top 5% of the engine's own posterior for 0/23 subjects. To decide what this means, three permutation nulls were pre-registered and run (100 draws per subject): a date-only shuffle (the battery null), a joint type+date scramble, and — added after review feedback, before any cohort result — an age-window null that replaces each event's date with a new date drawn from a type-appropriate age window (marriage 16–60, childbirth 16–55, career 18–85, accident 0–100, etc.), preserving life-course structure while keeping real power. A fourth same-type-only shuffle proved degenerate (zero power) and is recorded as such.
| Null (per subject × 100 draws) | Null mean recorded percentile | Pooled p(real ≤ null) |
|---|---|---|
| Age-window (powered, life-course-preserving) | 59.7 | 0.990 |
| Joint type+date scramble | 59.4 | 0.990 |
| Date-only shuffle (battery) | 63.2 | 0.976 |
| Same-type date shuffle | 69.5 (≡ real) | degenerate — zero power |
Real event dates place the recorded birth minute significantly worse than scrambled dates, and this survives a powered null that preserves life-course structure (p = 0.99). That is an anti-signal, not a null: the classical mapping as operationalised does not merely fail to find the recorded time — applied to these event lists it actively prefers other times of day, and the preference is robust across every reasonable way of constructing the comparison. Only 5/23 subjects rank better than their own age-window null (Albert II, Bush, Diana, George VI, JFK), which is what chance would scatter.
The one near-miss, examined. Einstein's Engine-B winner is 12:17 against his recorded 11:30 — Δ47 minutes, the closest any engine version has come, with 82% of posterior mass within ±60 minutes. It is not evidence. A single subject out of 23 landing within ±47 minutes is exactly what noise produces (expected ≈1.5 such subjects under a random winner; observed 1), his recorded minute does not beat his own age-window null (28th vs 21st percentile mean), and the specific channels that produced the 12:17 peak (divisional-lagna + Pratyantar) worsened the recorded-minute rank on 14/23 other subjects. The classical reading of Einstein's events is "cleanest" at 12:17 — which is precisely what a wrong but well-structured model produces.
What this study proves, and what it does not
- Established (narrowly). The core arithmetic of classical event-based rectification — Vimśottarī daśā lordship over event bhāvas from the lagna, with natural karakas and occupancy, at whole-sign level under Pushya Pakṣa — recovers no minute-level birth-time signal from day-granular event lists of this kind (8+ dated events per life). Under an additive scoring it performs at chance and cannot beat its own date-permutation null; under a rarity-weighted likelihood formalisation it performs significantly worse than chance; adding the Chandra frame, Pratyantar-daśā and divisional-lagna channels does not change that.
- Established (methodologically). Apparent successes in this domain must be treated as frame artefacts until demonstrated otherwise: the only out-of-sample band-hit in this cohort exists under one ayanāṁśa and not the mainstream one; the recorded time itself can be the error (Churchill is A-grade, not AA); and when an LLM is used to interpret event meaning before scoring, its draw-to-draw variance (15 h) exceeds any effect being measured.
- Not proven — and important to say so. This is a test of one operationalisation of one layer. It is not a test of (a) the full classical method as a human rectifier practises it, which adds interpretive judgment over the same evidence; (b) transits (gochara) as an event trigger, classically judged from the Moon with Saturn/Jupiter/Rahu/ Ketu — the layer that supplies the trigger within the daśā era and which this study does not test (it is the subject of the companion gochara study, linked at the end); (c) the navāṁśa-lagna and other divisional lagna as anchor methods, which use the fast-moving divisional ascendant itself rather than a lordship score; (d) the classical Prāṇapada positional rule, micro-points, or finer event evidence (sub-day timestamps). It is not a test of whether astrology's other claims (personality matching, transits, etc.) hold. It is equally not a claim that the recorded times are wrong: Einstein's AA anchor failed the method, and the method's failure on a sound anchor is evidence against the method as built.
- What the anti-signal suggests. When a model built from classical rules is worse than its own scrambled control on real data, the most probable readings are a systematic mismatch between the rules as coded and whatever the events actually record (event type labels carry residual LLM noise), or a genuine incompatibility between day-granular life events and a daśā-boundary signal that operates at finer granularity. Both readings were taken up in the companion gochara study — evidence at higher time resolution and the trigger layer itself — rather than further re-weighting of the same terms; its result is linked at the end.
Limitations
- Only the daśā–lordship core was tested here. Vargas as corroborating score terms (Engine B), yes; varga-lagna-as-anchor, classical Prāṇapada, hora/micro-pins — no. Gochara triggers are not tested in this article: they are the subject of the companion study linked below. A negative on the core is not a negative on the layers — but the layers that have now been run are reported there, not assumed.
- Day-granular events, famous subjects. Eight dated events per life, each known only to the day, is thin compared with what a practitioner elicits from a client, and public-figure event lists are third-party constructions with their own type-label noise. Both limitations bias toward null — they do not explain an anti-signal.
- Ayanāṁśa and frame. Production frame is Pushya Pakṣa; Lahiri (mainstream) was run as the falsification cell and returns 0/23. Mean nodes throughout. The frame sensitivity of winners (23/23) is itself a finding: minute-level claims built on sign boundaries inherit ~24° of frame uncertainty.
- Anchors. AA at collection for 21/23; Churchill re-rated A (his failure and his re-rating are both documented); Einstein's AA verified. A systematic re-audit of the remaining twenty-one is queued. Anchor error cannot produce the cohort-level anti-signal (bad anchors flatten toward noise), but per-subject readings should not outrun the audit.
- The Prāṇapada correction of record. A tuning term previously described as a Prāṇapada micro-layer was audited and found non-classical; it is excluded from all subsequent engines. The headline Engine-A runs and their headline statistics (mean rank 754 vs null 720.5) were computed with the term still active, for continuity with the original tuning history; the PP-excluded control is 835, reported in the falsification battery table. No subsequent engine or likelihood analysis uses the term.
- n = 23. Sufficient to show chance-level (and worse-than-chance) performance; it cannot bound a small real effect tightly, and the anti-signal's effect size (10 percentile points) should be read with that in mind. No formal power analysis is reported; the cohort was sized to detect large effects at ±30 minutes, not to bound a small real effect or to distinguish underpowering from a genuine null.
- Engine, not astrologer. A mechanical engine cannot reproduce a practitioner's interpretive judgment, and a null here is not automatically a null for a skilled human reading the same chart. It is, however, the objective instrument a service would actually deploy, and the study exists to gate that deployment.
Follow-up — the gochara study: run, and published in full
The layer this study did not test — and the classical tradition's own answer to "when, within the era, does the event actually arrive" — is gochara (transits): the doctrine, carried in Bṛhat Parāśara Horā Śāstra and standard practice, that Saturn, Jupiter, Rahu, Ketu and (secondarily) Mars, judged from the natal Moon sign and from the lagna, trigger the events the daśā period promises; refined classically by Aṣṭakavarga and in modern software by exact-degree conjunctions. That study has now been run to completion — three pre-registered stages on this same 23-subject cohort and machinery. The headline result, reported in full in the companion article (Transits as Event Triggers: A Three-Stage Test): raw gochara recovered 0/23 birth times within ±30 minutes, with a candidate concentration (4/23 in the top 5% of their own day, p = 0.026) that did not beat a life-course-preserving null (pooled p = 0.73); the Aṣṭakavarga refinement failed its pre-registered gate on every arm and degraded the ranking it was meant to refine; and the hour-level Moon channel, tested on nineteen independently minute-dated events across eight AA-anchored charts, produced 0/19 fires at the documented event minutes (p = 1.0000 against the hour-shuffle null). A programme-wide synthesis of all four layers — daśā, raw gochara, Aṣṭakavarga and the Moon, with the one untested rung (event-moment angles) — is published as Classical Event Timing at Every Resolution. Negative or positive, everything is reported in full, per the standing rule.
Study timeline
| Period (2026) | Step | Outcome |
|---|---|---|
| pre-09-01 | Protocol written (pass rule, blinding, anchor doctrine) | Design locked before any run |
| 09-01 → 09-05 | Runs 1–13 (v1.0.0 → v1.5.0, tuned on Jobs); H1 named; tz audit; 10-subject expansion; v2.0.0 Varga matrix in- and out-of-sample | Cohort at chance; OOS 1/22; v2.0.0 = 0/10 |
| 09-07 | Five frontier-model external reviews → falsification battery (date-permutation, ayanāṁśa grid, PP ablation, typing variance) + anchor audit | Real events indistinguishable from date-shuffle null; Lahiri 0/23; Churchill re-rated A; PP corrected |
| 09-07 | Engine B (likelihood) pre-registered, built, run on the cohort; null ladder incl. age-window null | 0/23; anti-signal robust across nulls (p ≈ 0.99); coverage 0/23 top-5% |
| 09-07 | Four follow-up reviews of the anti-signal; null repaired per objection; results documented; this revision published | Anti-signal stands; classical core closed under two formalisations |
| 09-07 | Gochara study run to completion (raw transits, Aṣṭakavarga, timed-event Moon layer) and published as the companion article | 0/23 recoveries; AV degrades; Moon 0/19 at documented minutes — see companion article |
Reproduction
The complete study is published with this article: the protocol and both engine specs (committed before their runs), the subjects file with birth-data sources and the anchor audit, every run payload and result, the battery and null harnesses (all deterministic, zero LLM calls in any ranking path), the per-subject diagnostics, the Stage-A variance probe, and the versioned engine changelog — so that every number above traces to the exact code that produced it. Research repository: RESEARCH/birth-time-rectification-study/ in the project repository (Pushya Pakṣa engine). All negatives published in full, per the standing rule of the ATRAC Institute research programme.
Revised and re-published 2026-09-07 incorporating the falsification battery, the likelihood reframe, the anchor audit and the correction of record on Prāṇapada. This study is scientific research on the measurable claims of a planned service, published by the ATRAC Institute's Sidereal Telemetry Lab. It is not a validation of any astrological product and nothing in it should be read as a recommendation to rely on any astrological service. The rectification service remains closed until a protocol-fixed accuracy gate is met.